Data engineering is becoming increasingly important as businesses collect information from websites, applications, cloud platforms, databases, and enterprise systems. Managing this growing volume of data requires efficient ways to integrate, process, transform, and deliver information for business intelligence and analytics.
Traditional data engineering often involves extensive programming, complex integrations, and continuous maintenance. However, low-code and no-code platforms are changing how organizations approach these processes by introducing visual development environments, prebuilt connectors, reusable components, and workflow automation.
These platforms help businesses simplify data integration, automate ETL processes, develop data pipelines, and improve collaboration between technical and non-technical teams. They also complement professional
Data Engineering Services by helping engineering teams accelerate development and manage repetitive data workflows.
But what is the difference between low-code and no-code platforms? How do they support modern data engineering, and which approach should businesses choose?
In this guide, we explore how low-code vs. no-code platforms are transforming data engineering in 2026, including their differences, benefits, limitations, popular tools, real-world applications, and future developments.
Key Takeaways
- Low-code platforms combine visual development with custom programming capabilities.
- No-code platforms allow users to build supported workflows and applications without traditional coding.
- Both approaches can simplify data integration, data preparation, ETL/ELT workflows, and automation.
- AI-assisted development is expanding how teams create and manage data workflows.
- Security, scalability, data quality, governance, and vendor lock-in remain important considerations.
- Combining low-code tools with traditional development can help businesses manage complex enterprise data requirements.
What Are Low-Code and No-Code Platforms?
Low-code and no-code platforms are development environments that help users build applications, automate workflows, and connect different systems using visual interfaces and prebuilt components.
Instead of manually writing every line of code, users can configure workflows, connect data sources, apply transformations, and automate business processes through graphical tools.
Although both approaches aim to simplify development, they differ in the amount of programming flexibility and technical control they provide.
What Is Low-Code Development?
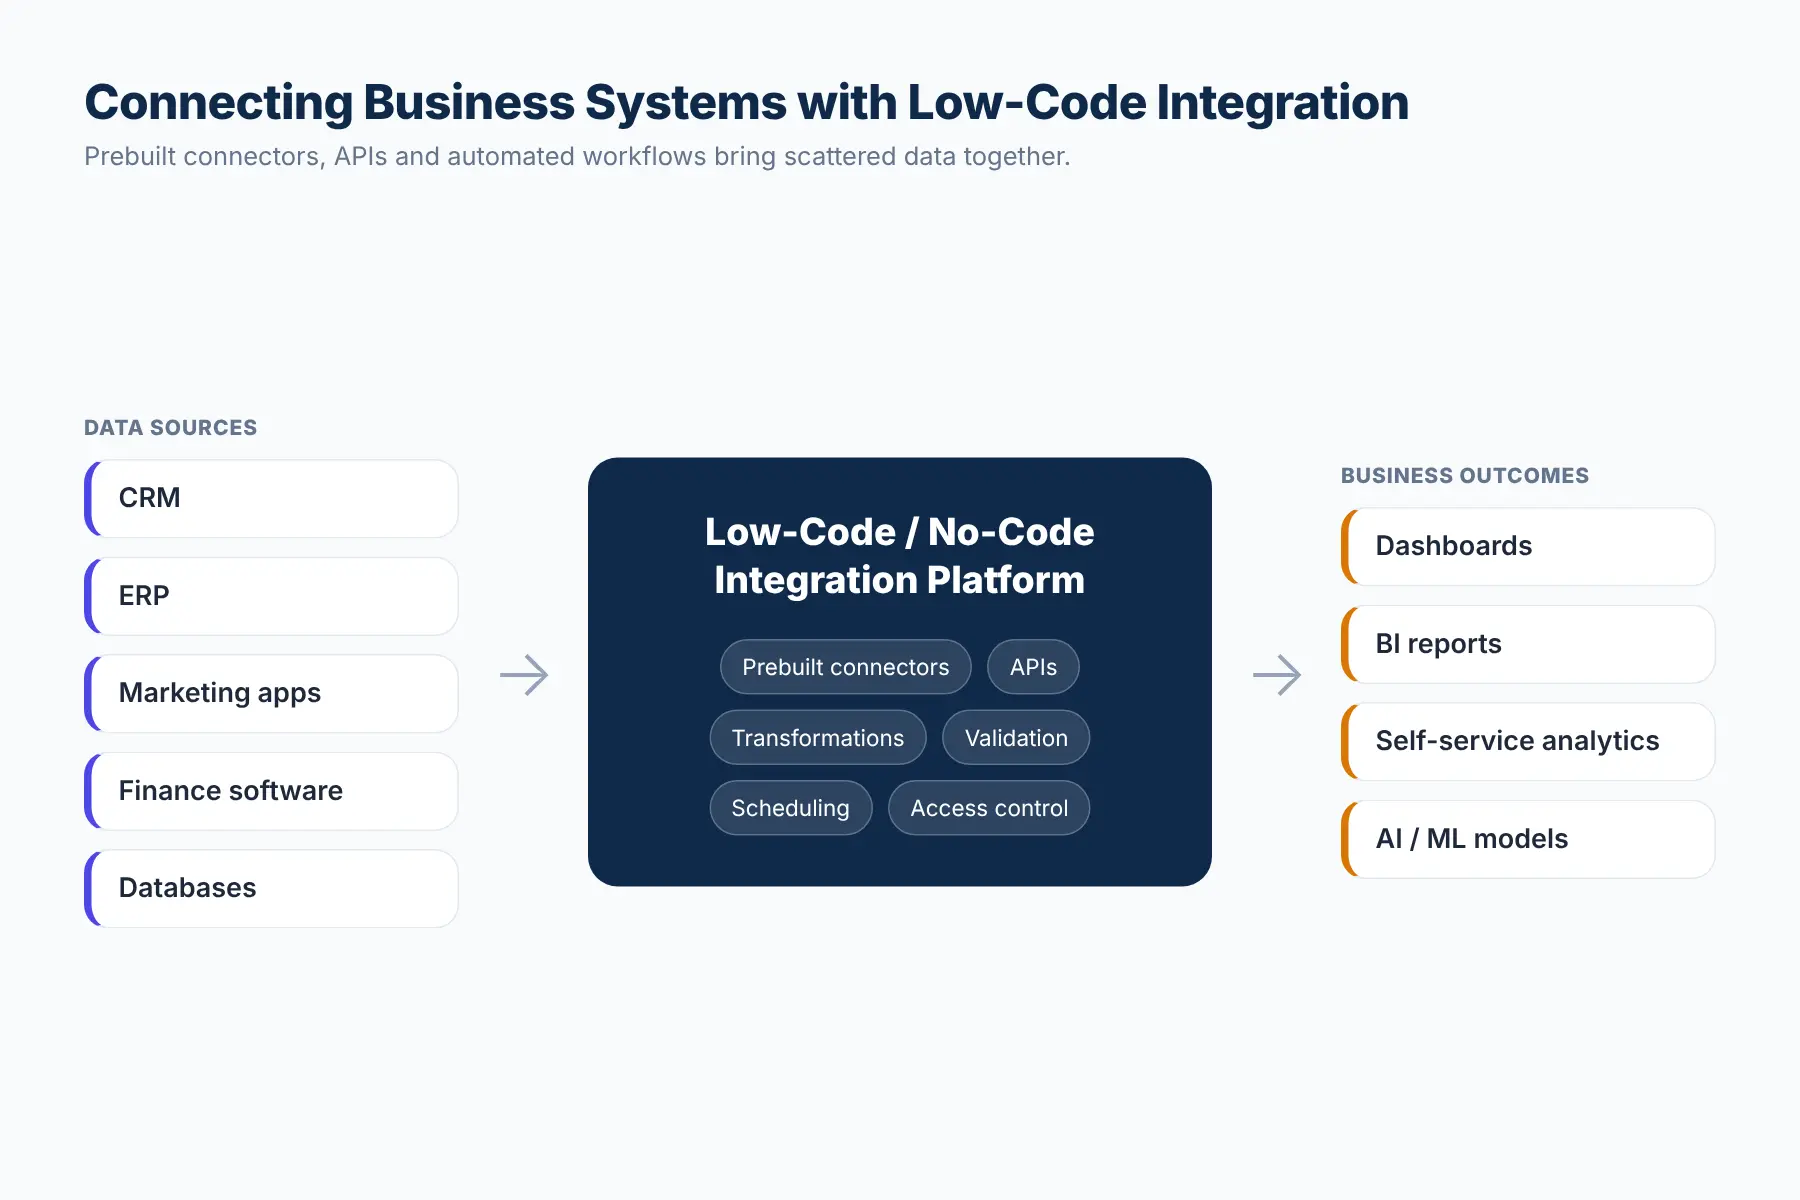
Low-code development is an approach that allows users to create applications, integrations, and automated workflows primarily through visual development tools, with the option to add custom code when necessary.
These platforms combine drag-and-drop interfaces, reusable components, prebuilt connectors, APIs, and programming capabilities.
For example, a data engineering team can use a visual ETL interface to connect databases, configure transformations, and transfer information into a cloud data warehouse. If the workflow requires specialized processing, developers can introduce custom SQL, Python, or other supported code.
Key characteristics of low-code development include:
- Visual development environments
- Drag-and-drop functionality
- Prebuilt connectors and reusable components
- Support for custom programming
- API and database integrations
- Workflow automation
- Greater flexibility for complex business requirements
Low-code platforms are particularly useful for organizations that want to accelerate development while maintaining technical control.
What Is No-Code Development?
No-code development allows users to create applications, automate business processes, and connect systems without writing traditional programming code for supported tasks.
These platforms generally provide visual workflow builders, configurable templates, prebuilt integrations, and user-friendly interfaces.
For example, a business analyst can create an automated workflow that collects information from an online form, transfers it into a spreadsheet, and sends a notification when a new record is submitted.
Key characteristics of no-code development include:
- No traditional programming required for supported workflows
- Visual workflow builders
- Preconfigured templates
- Ready-to-use connectors
- Simplified application development
- Automated business processes
- Accessibility for non-technical users
No-code platforms are useful for straightforward automation and routine business processes that do not require extensive customization.
Low-Code vs. No-Code: What Is the Difference?
Low-code and no-code platforms share the goal of simplifying development, but they serve different technical requirements.
The main difference is the level of customization and programming flexibility available.
| Comparison factor |
Low-code platforms |
No-code platforms |
| Coding requirements |
Minimal coding, with custom code support |
No traditional coding for supported tasks |
| Target users |
Developers, IT teams, technical users |
Business users, analysts, non-technical teams |
| Customization |
Generally more flexible |
Depends on available platform features |
| Development approach |
Visual tools combined with programming |
Visual configuration and templates |
| Integrations |
Supports advanced integrations depending on the platform |
Primarily supported connectors and integrations |
| Flexibility |
Suitable for more complex requirements |
Best for predefined workflows |
| Maintenance |
May require developer involvement |
Often manageable through configuration |
| Common applications |
Enterprise applications, custom integrations, data workflows |
Basic automation, forms, routine business processes |
Which Is Better: Low-Code or No-Code?
Neither approach is universally better. The right choice depends on the complexity of the project and the technical requirements.
No-code is generally suitable for straightforward workflows that business users can manage independently.
Low-code is more appropriate when applications or integrations require custom logic, advanced configurations, or greater developer control.
For enterprise data engineering, low-code solutions and traditional programming can work together to support more complex architectures.
How Are Low-Code and No-Code Platforms Transforming Data Engineering?
Data engineering involves collecting information from multiple sources, transforming it into usable formats, maintaining data quality, and making it available for reporting and analytics.
Low-code and no-code platforms simplify several activities within this process.
1. Simplifying Data Pipeline Development
Data pipelines move information from source systems to databases, data lakes, and data warehouses.
Traditionally, engineers needed to write scripts, configure integrations, develop transformations, and manage individual pipeline components.
Low-code platforms simplify supported tasks through visual pipeline builders, reusable components, and prebuilt connectors.
For example, a business can create a workflow that:
- Extracts customer information from a CRM system.
- Connects the data to a cloud storage environment.
- Applies predefined transformation rules.
- Loads processed information into a data warehouse.
- Makes the resulting datasets available for analytics.
This approach makes pipeline development easier to configure and understand.
However, complex data pipelines may still require custom code, advanced orchestration, and performance optimization.
2. Automating ETL and ELT Processes
ETL (Extract, Transform, Load) and ELT (Extract, Load, Transform) are essential processes in modern data integration.
They help businesses collect information from different systems, transform it into usable formats, and make it available for analytics.
Low-code platforms provide visual tools that help teams configure these workflows without manually developing every integration component.
For example, an organization can:
- Extract information from databases and business applications.
- Load raw data into a cloud data warehouse.
- Apply transformation rules.
- Validate processed datasets.
- Schedule recurring data workflows.
AWS Glue Studio is one example of a service that provides visual ETL development capabilities.
The appropriate approach depends on data volume, processing requirements, architecture, and integration complexity.
3. Improving Data Integration Across Business Systems
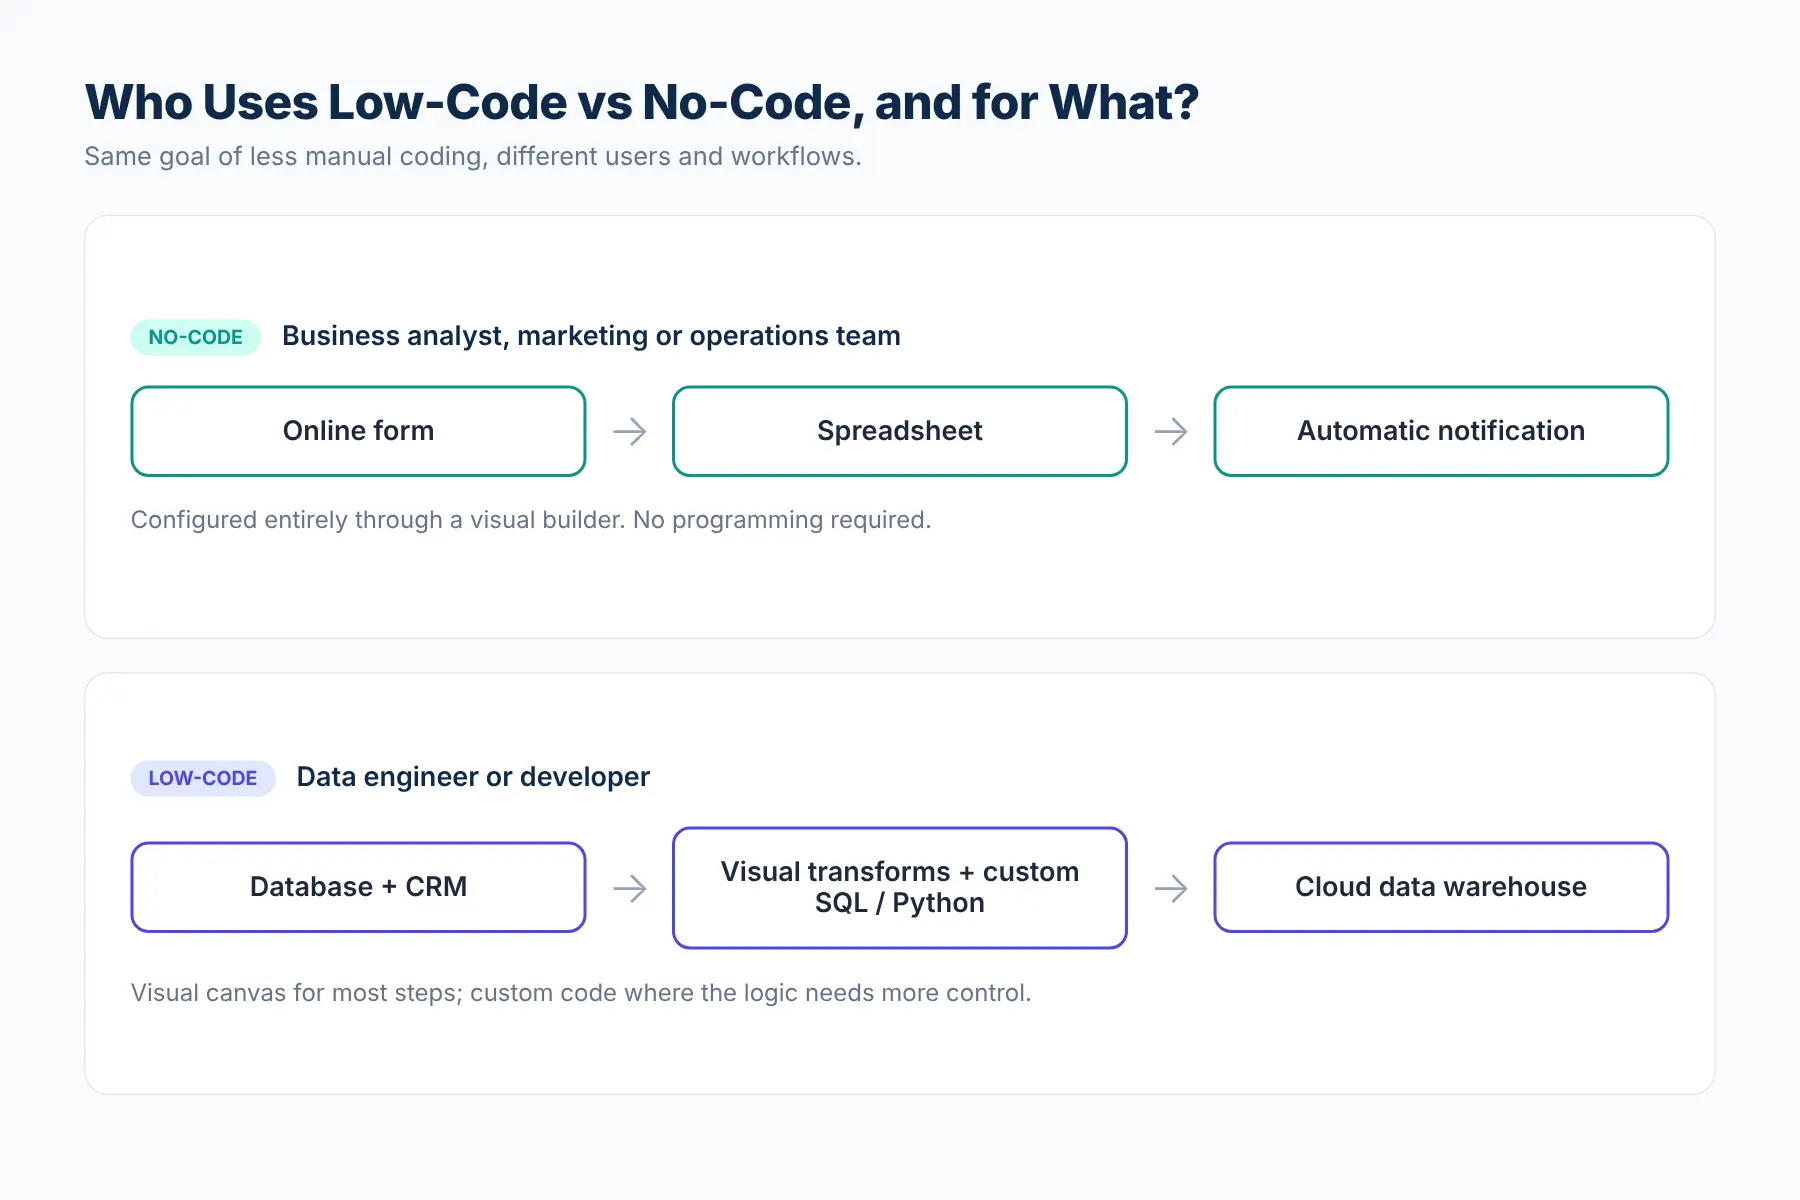
Organizations often store information across CRM platforms, ERP systems, marketing applications, financial software, and cloud databases.
When these systems operate independently, businesses may experience duplicated records, inconsistent information, and disconnected reporting.
Low-code and no-code integration tools can connect supported systems through prebuilt connectors, APIs, and automated workflows.
For example, a company can synchronize customer records between its CRM system and an analytics environment, helping reporting teams work with more consistent information.
This can improve:
- Data accessibility
- Information synchronization
- Cross-platform communication
- Reporting consistency
- Operational efficiency
For complex enterprise environments, integration architecture must also account for authentication, API limits, data mapping, and error handling.
4. Making Data Preparation More Accessible
Raw data is not always ready for business analysis.
It may contain duplicate records, missing values, inconsistent formats, or incorrect data types.
Data preparation involves cleaning, validating, standardizing, and organizing information before it is used for reporting and analytics.
Visual data preparation tools allow users to perform supported transformations through configurable interfaces.
Common activities include:
- Removing duplicate records
- Standardizing date and number formats
- Filtering unnecessary information
- Combining datasets
- Handling missing values
- Renaming and restructuring fields
These capabilities help analysts prepare information more efficiently.
However, businesses still need data validation rules and quality checks to ensure that automated transformations produce accurate results.
5. Supporting Self-Service Analytics
Traditional data workflows often require business users to request datasets and reports from data engineering teams.
This can create delays when analysts need information for recurring business decisions.
Low-code and no-code platforms can support self-service analytics by making approved datasets and workflows more accessible.
For example, marketing teams can monitor campaign performance through connected dashboards, while sales teams can analyze customer
trends using governed data sources.
This helps business users explore information without requiring engineers to manually prepare every report.
Organizations can also combine reliable data pipelines with Data Analytics Services to turn integrated business information into actionable reports, dashboards, and insights.
Self-service analytics should always follow appropriate access permissions and data governance policies.
6. Improving Collaboration Between Technical and Non-Technical Teams
Data engineering projects involve multiple stakeholders, including developers, data analysts, business managers, and IT administrators.
Miscommunication between these teams can lead to incorrect requirements, repeated development work, and project delays.
Visual development environments make data workflows easier to understand and discuss.
Business analysts can communicate their requirements through visual workflows, while data engineers review the architecture, validate the logic, and implement advanced components when needed.
This encourages better collaboration between business and technical teams.
7. Enabling AI-Assisted Data Workflows
Artificial intelligence is expanding the capabilities of modern development platforms.
AI-assisted features can help developers and business users generate workflow suggestions, create application components, automate repetitive configuration tasks, and work with data through natural-language instructions.
Potential applications include:
- Generating workflow configurations
- Suggesting data transformation steps
- Assisting with SQL and code generation
- Identifying potential data quality issues
- Generating technical documentation
- Supporting automated application development
However, AI-generated workflows must be reviewed before deployment.
Data engineers should validate generated code, test transformations, review permissions, and ensure that automated processes meet security and compliance requirements.
AI can accelerate development, but it does not eliminate the need for engineering expertise.
Popular Low-Code and Data Integration Tools in 2026
The right platform depends on the type of workflow, existing technology stack, technical expertise, data architecture, and business requirements.
The following tools serve different purposes within data integration, workflow automation, and application development.
1. AWS Glue Studio
AWS Glue Studio provides a visual interface for creating, running, and monitoring ETL jobs in AWS Glue.
Users can configure data sources, transformations, and destinations through a visual editor. The platform can generate scripts for processing jobs, and developers can also work with custom scripts.
Key capabilities:
- Visual ETL job development
- Data source and destination configuration
- Data transformation
- Job scheduling and monitoring
- Integration with AWS data services
Best suited for: Organizations building data integration and processing workflows within the AWS ecosystem.
2. Google Cloud Data Fusion
Google Cloud Data Fusion is a managed, cloud-native enterprise data integration service.
It helps business users, developers, and data scientists create and manage data pipelines for cleansing, preparing, transferring, blending, and transforming information.
Key capabilities:
- Visual data pipeline development
- Data integration
- Data transformation
- Cloud-based processing
- Pipeline management
Best suited for: Businesses building data integration workflows within Google Cloud environments.
3. Microsoft Power Platform
Microsoft Power Platform provides low-code tools for building business applications, automating processes, and analyzing information.
Its products serve different business requirements:
- Power Apps: Build custom business applications.
- Power Automate: Automate tasks and business processes.
- Power BI: Analyze information and create interactive reports.
- Dataverse: Manage business data for connected applications.
- Copilot Studio: Build AI-powered agents and workflows.
Best suited for: Organizations that want to automate business processes, develop internal applications, and connect business workflows within the Microsoft ecosystem.
4. Mendix
Mendix is a low-code application development platform that helps organizations create and manage business applications using visual development tools.
It can be useful when data engineering initiatives also require custom business applications, connected workflows, or enterprise application integrations.
Key capabilities:
- Visual application development
- Business workflow development
- Application integration
- Reusable application components
- Enterprise application development
Best suited for: Organizations developing custom business applications and connected enterprise workflows.
5. Retool
Retool is a low-code development platform for building internal business applications and tools.
It allows developers to connect databases and APIs and create interfaces for working with business information.
Key capabilities:
- Internal application development
- Database and API connections
- Custom business interfaces
- Workflow automation
- Developer customization
Best suited for: Engineering and operations teams that need internal tools connected to databases and business systems.
Important: These platforms are not direct substitutes for one another. AWS Glue Studio and Google Cloud Data Fusion focus on data integration and pipeline development, while Microsoft Power Platform, Mendix, and Retool primarily support application development, automation, or business workflows. Evaluate them according to your specific requirements.
Real-World Use Cases of Low-Code and No-Code in Data Engineering
Low-code and no-code platforms can support several business processes when used within their technical and operational limitations.
Use Case 1: Customer Data Integration
A business collects customer information from its website, CRM system, and marketing applications.
Integration workflows can connect these sources, synchronize records, and prepare customer information for analytics.
Business value:
Improved data accessibility and reduced manual data consolidation.
Use Case 2: Financial Reporting Automation
Finance teams often work with information from accounting applications, spreadsheets, and transaction systems.
Automated workflows can collect and consolidate this information before it reaches reporting dashboards.
Business value:
More consistent reporting processes and reduced repetitive data handling.
Use Case 3: Marketing Analytics
Marketing departments need information from advertising platforms, CRM systems, and website analytics tools.
Integration workflows can bring these sources together so analysts can evaluate campaign performance.
Business value:
Better access to campaign information and more informed marketing decisions.
Use Case 4: Data Preparation for Business Intelligence
Organizations need to clean and organize datasets before using business intelligence tools.
Visual data preparation workflows can standardize formats, remove duplicates, and combine approved datasets.
Business value:
More consistent information for dashboards and reporting.
Use Case 5: Inventory Data Synchronization
Retail and manufacturing businesses may manage inventory information across ERP systems, warehouses, and sales applications.
Automated integrations can synchronize supported records between these systems and make inventory information easier to monitor.
Business value:
Improved operational visibility and reduced manual data entry.
Benefits of Low-Code and No-Code Platforms for Businesses
When implemented appropriately, low-code and no-code platforms can provide several operational advantages.
1. Faster Development and Deployment
Prebuilt components, visual interfaces, and reusable templates can reduce repetitive development work.
This helps teams build supported applications and data workflows more efficiently.
2. Reduced Manual Work
Workflow automation can minimize repetitive activities such as transferring records, preparing datasets, and synchronizing information between applications.
3. Improved Business and IT Collaboration
Visual development environments help technical and non-technical stakeholders understand workflows and communicate requirements.
4. Better Accessibility to Data
Governed self-service workflows can help authorized business users access and prepare information without depending on engineering teams for every routine request.
5. Greater Business Agility
Organizations can modify supported workflows as business requirements change, helping them respond to evolving operational needs.
6. More Efficient Use of Engineering Resources
By reducing repetitive configuration tasks, data engineers can dedicate more time to architecture, complex integrations, data quality, security, and performance optimization.
The actual benefits depend on platform capabilities, implementation quality, and the complexity of the workflows being automated.
Challenges and Limitations of Low-Code and No-Code Platforms
Despite their advantages, these platforms are not suitable for every data engineering requirement.
Businesses should evaluate the following challenges before implementation.
1. Data Security and Privacy Risks
Integration platforms may connect multiple business applications and databases.
Incorrect access permissions, authentication settings, or data-sharing policies can expose sensitive information.
How to address this challenge:
- Implement role-based access control.
- Use secure authentication mechanisms.
- Encrypt sensitive information.
- Review integration permissions.
- Conduct regular security assessments.
2. Limited Customization
No-code platforms generally restrict development to their supported features, templates, and connectors.
This can create difficulties when an organization requires advanced transformation logic, specialized APIs, or custom processing.
How to address this challenge:
Choose a platform that supports extensibility, custom integrations, and a hybrid development approach where necessary.
3. Scalability and Performance Constraints
A workflow that works well with a small dataset may not perform efficiently when data volumes increase.
Processing limits, API restrictions, infrastructure configuration, and platform architecture can affect performance.
How to address this challenge:
Evaluate data volume, concurrency, processing requirements, workload limits, and scaling capabilities before implementation.
4. Vendor Lock-In
Some platforms rely on proprietary components, workflow definitions, and connectors.
Moving integrations and business processes to another platform may become difficult when portability is limited.
How to address this challenge:
Review data export options, API availability, documentation, code ownership, and migration requirements.
5. Data Governance and Quality Issues
Allowing multiple departments to create independent workflows can lead to inconsistent data definitions, duplicated datasets, and uncontrolled access.
It can also increase shadow IT and technical debt.
How to address this challenge:
Establish centralized governance policies, approved data sources, ownership responsibilities, documentation standards, and validation procedures.
6. Platform Dependency and Maintenance
Organizations may depend on platform providers for infrastructure, product updates, connector availability, and technical support.
Changes in pricing, functionality, or service availability can affect existing workflows.
How to address this challenge:
Evaluate service-level agreements, support options, pricing models, platform roadmaps, and migration strategies.
Low-Code vs. No-Code vs. Traditional Coding: Which Approach Should You Choose?
Businesses do not always need to select one development approach for every project.
The best option depends on workflow complexity, performance requirements, technical expertise, and long-term maintenance needs.
| Requirement |
No-code |
Low-code |
Traditional coding |
| Basic workflow automation |
Excellent fit |
Suitable |
Possible but often unnecessary |
| Simple data integration |
Suitable when supported |
Suitable |
Suitable |
| Custom business logic |
Limited |
Strong fit |
Strong fit |
| Complex data pipelines |
Depends on platform limits |
Suitable with extensibility |
Strong fit |
| Specialized data processing |
Limited |
Depends on custom-code support |
Strong fit |
| Advanced performance optimization |
Platform-dependent |
Greater flexibility |
Greater control |
| Enterprise-specific architecture |
Depends on platform |
Often suitable |
Strong fit |
When Should You Choose No-Code?
Choose no-code when:
- Business users need to automate straightforward workflows.
- Required connectors are already available.
- Custom programming is unnecessary.
- Data volumes and processing requirements are manageable.
- Workflows can operate within the platform's security and governance controls.
When Should You Choose Low-Code?
Choose low-code when:
- Workflows require custom business logic.
- Developers need visual tools and programming flexibility.
- Multiple enterprise applications must be integrated.
- Data transformation requirements are more advanced.
- The business needs greater control over application and workflow development.
When Is Traditional Coding the Better Option?
Traditional coding is often appropriate when:
- Data processing requirements are highly specialized.
- Large-scale distributed processing is necessary.
- Complex algorithms or custom integrations are required.
- Fine-grained performance optimization is important.
- The architecture requires extensive customization.
For many enterprise organizations, a hybrid approach offers the most flexibility. Low-code and no-code platforms can simplify routine tasks, while developers handle complex pipelines, security controls, custom transformations, and performance-critical components.
How to Choose the Right Low-Code or No-Code Platform
Selecting a platform involves more than comparing visual features or development speed.
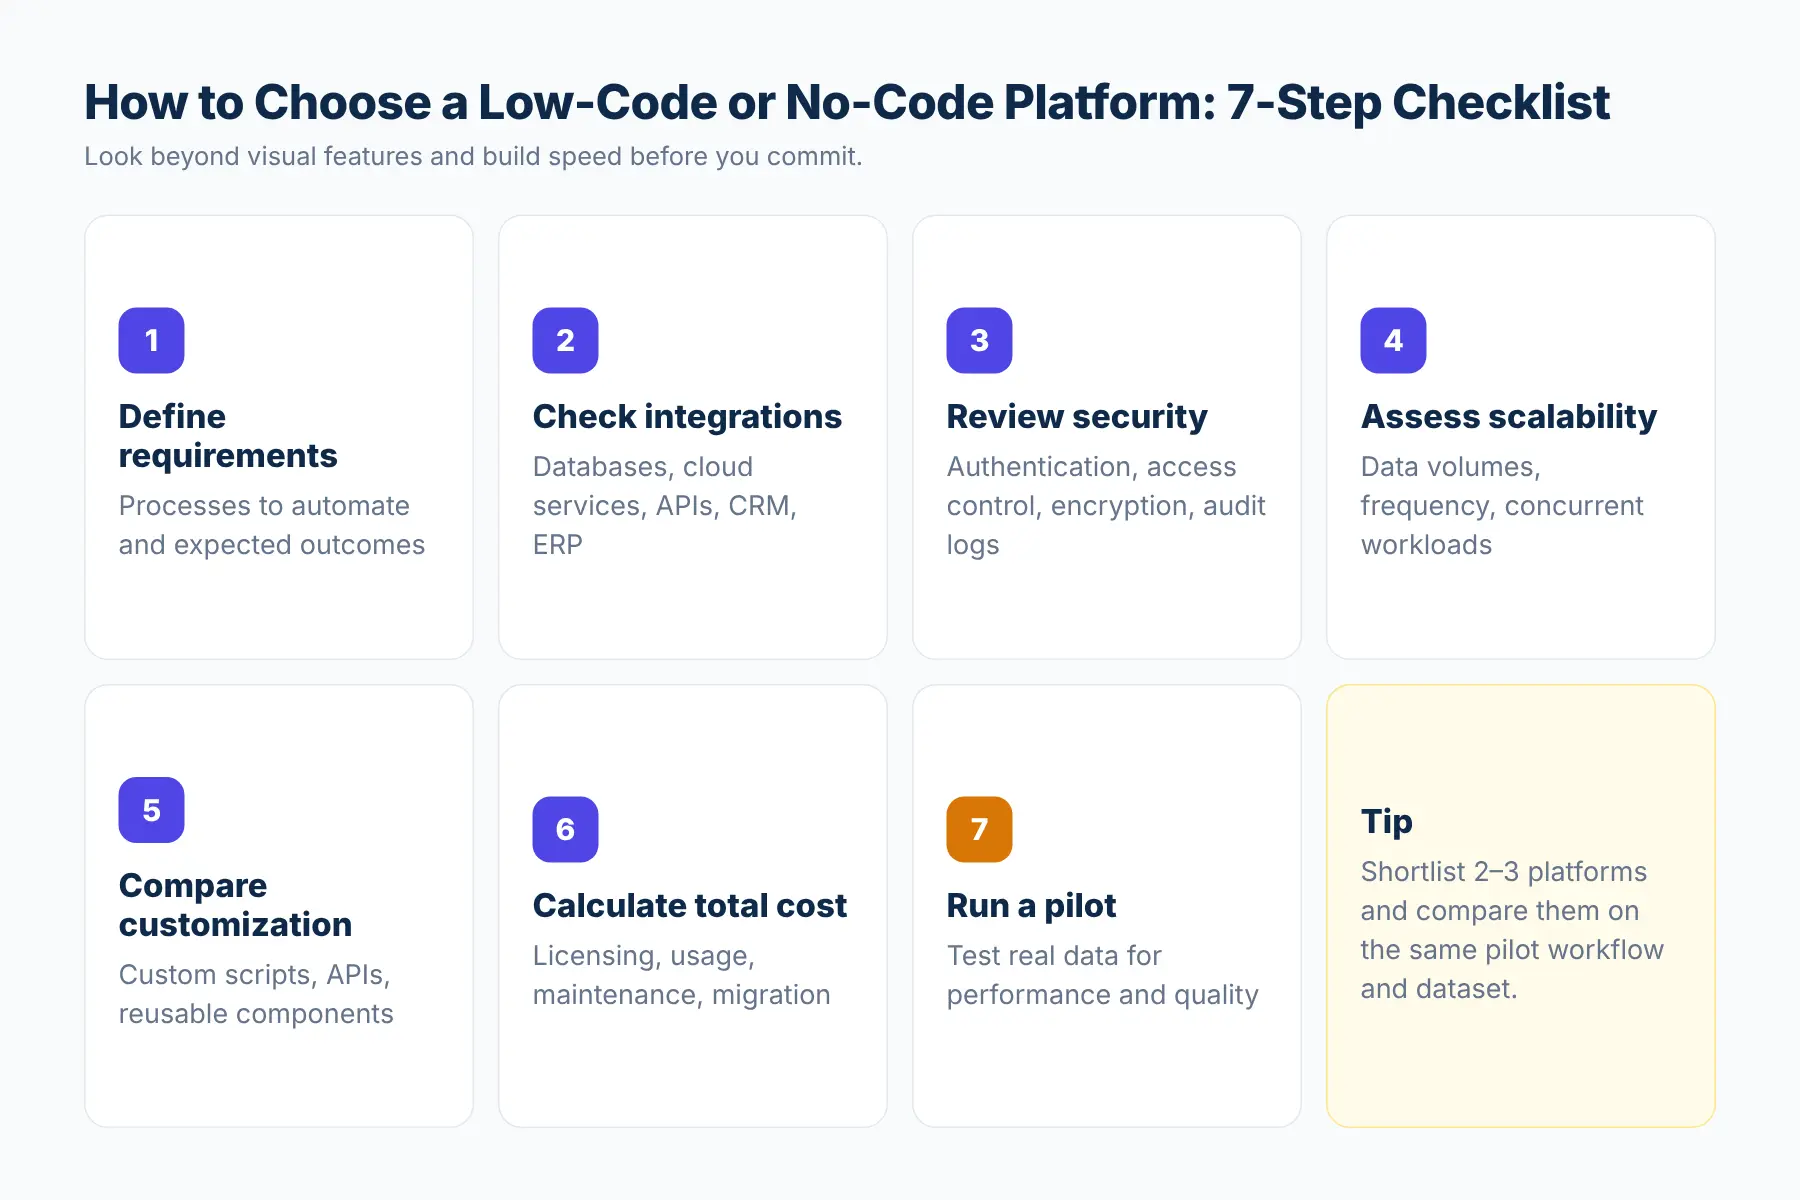
Before making a decision, consider these factors.
1. Define Your Business Requirements
Identify which processes you want to automate and what outcomes you expect.
Determine whether the platform will support data integration, pipeline development, reporting, application development, or workflow automation.
2. Evaluate Integration Capabilities
Check whether the platform connects with your existing databases, cloud services, APIs, CRM systems, and enterprise applications.
3. Review Security and Governance Features
Evaluate authentication, access control, encryption, audit logs, compliance requirements, and data management capabilities.
4. Assess Scalability
Consider expected data volumes, processing frequency, concurrent workloads, and future business growth.
5. Compare Customization Options
Determine whether the platform supports custom scripts, APIs, reusable components, and advanced transformations.
6. Understand Total Cost of Ownership
Evaluate licensing, infrastructure, usage-based charges, integration development, maintenance, support, and migration costs.
7. Test Before Full Implementation
Run a pilot project using representative datasets and workflows.
Measure performance, reliability, data quality, security, and ease of maintenance before expanding the implementation.
How to Choose the Right Data Engineering Company or Service Provider
Selecting the right technology partner is important when your organization needs more than basic workflow automation.
A reliable
data engineering company can help assess your existing infrastructure, identify integration challenges, design scalable data pipelines, and implement solutions that align with your business objectives.
When comparing data engineering service providers, consider the following factors:
1. Technical Expertise and Experience
Evaluate the provider's experience with cloud platforms, databases, ETL/ELT processes, data warehouses, data pipelines, and integration technologies.
2. Data Engineering and Analytics Capabilities
Look for a provider that understands both data infrastructure and business analytics requirements.
For example, combining data engineering consulting services with data analytics consulting can help organizations establish reliable data pipelines and turn integrated information into useful business insights.
3. Security and Data Governance
Check whether the provider follows appropriate security practices, access management policies, data protection requirements, and governance standards.
4. Scalability and Customization
Choose a partner that can design solutions according to your current data requirements while supporting future business growth.
5. Flexible Engagement Models
Understand whether the provider offers project-based development, dedicated engineering teams, consulting, or ongoing maintenance.
6. Communication and Ongoing Support
Evaluate project communication, documentation, maintenance capabilities, and technical support before making a decision.
Businesses looking for a Data Engineering Company in USA should also consider industry experience, time-zone compatibility, communication processes, and the provider's ability to support US business and regulatory requirements.
The goal is not simply to find a vendor that can configure a platform. It is to work with a technology partner that understands your complete data architecture and long-term business needs.
When Should You Hire Data Engineers or Data Developers?
Low-code and no-code platforms can simplify routine development activities, but they do not eliminate the need for skilled technical professionals.
Businesses may need to
hire data engineers when they require:
- Scalable data pipeline architecture
- Complex ETL and ELT development
- Cloud data warehouse implementation
- Data integration across enterprise systems
- Data quality and governance solutions
- Performance optimization and monitoring
Organizations may also hire data developers when they need professionals to build data-related applications, implement database logic, develop integrations, and support custom data processing requirements.
For smaller or specialized projects, working with an external engineering partner may provide access to the required expertise without building an entire in-house team.
What Is the Future of Low-Code and No-Code in Data Engineering?
Low-code and no-code development is evolving beyond visual workflow configuration. AI-assisted capabilities, cloud-based integration, automation, and stronger governance are shaping how businesses build and manage data workflows.
Several developments are particularly important.
1. AI-Assisted Development and Workflow Automation
AI can help developers and business users generate code suggestions, configure workflows, create application components, and automate repetitive tasks.
However, generated outputs still need testing, validation, security reviews, and human oversight before production deployment.
2. Greater Focus on Data Governance
As more departments build their own applications and automated workflows, organizations will need stronger governance frameworks.
Access control, data ownership, documentation, monitoring, and compliance will remain essential.
3. Expansion of Cloud-Based Data Integration
Cloud data integration services are making it easier to connect distributed data sources and manage processing workflows through visual environments.
Businesses will continue evaluating these services based on scalability, reliability, integration requirements, and cost.
4. Increased Adoption of Hybrid Development
Low-code and no-code tools are not complete replacements for traditional programming.
Instead, organizations can combine visual development with custom programming to balance development speed, flexibility, and technical control.
5. More Accessible Data Operations
Self-service data preparation, workflow automation, and governed analytics can help business teams work with information more independently.
However, greater accessibility must be supported by appropriate security, data quality, and governance controls.
How Can Spiral Mantra Help with Data Engineering Solutions?
Implementing low-code or no-code platforms is only one part of building an effective data engineering environment.
Businesses also need to consider data architecture, integration requirements, pipeline performance, security, and long-term scalability.
At Spiral Mantra, we understand the importance of building data solutions that align with business requirements and existing technology infrastructure.
Organizations exploring professional Data Engineering Services can benefit from evaluating their data integration requirements, modernizing existing workflows, and establishing reliable data pipelines.
In addition to data engineering, businesses may need Data Analytics Services to transform integrated information into meaningful reports, dashboards, and business insights.
From planning data infrastructure to improving data workflows, the right engineering and analytics strategy can help organizations make better use of their information.
Looking for a technology partner to improve your data infrastructure?
Connect with Spiral Mantra to discuss your data engineering requirements and explore solutions aligned with your business goals.
Frequently Asked Questions (FAQs)
Q1. What are the advantages of using low-code or no-code platforms?
Low-code and no-code platforms can accelerate supported development tasks, automate repetitive workflows, simplify data integration, and improve collaboration. They also make application development and workflow automation more accessible to non-technical users.
Q2. What is the main difference between low-code and no-code platforms?
Low-code platforms combine visual development tools with the ability to write custom code, while no-code platforms allow users to build supported applications and workflows without traditional programming. Low-code generally provides greater customization, whereas no-code focuses on accessibility and ease of use.
Q3. Can low-code and no-code platforms be used for data engineering?
Yes. They can support data integration, ETL/ELT workflows, data preparation, pipeline configuration, and business process automation. Complex data engineering requirements may still require custom programming and traditional engineering tools.
Q4. Will ETL be replaced by AI?
No. AI can assist with ETL development, transformation suggestions, data mapping, and workflow automation, but it does not eliminate the need for data integration and transformation processes. Organizations will continue to need reliable ETL and ELT architectures, data validation, security, and monitoring.
Q5. Will low-code and no-code platforms replace developers?
No. These platforms reduce the amount of manual coding required for supported tasks, but developers remain essential for complex integrations, application architecture, security, performance optimization, testing, and maintenance. Their roles may evolve toward higher-value engineering and platform governance.
Q6. What are the disadvantages of using no-code platforms?
Common disadvantages include limited customization, platform dependency, scalability constraints, integration limitations, vendor lock-in, and governance challenges. The extent of these limitations depends on the platform and the complexity of the business requirements.
Q7. Which platforms are useful for low-code data engineering?
AWS Glue Studio and Google Cloud Data Fusion are relevant options for visual data integration and ETL pipeline development. Microsoft Power Platform can support connected business applications and workflow automation. The right choice depends on the organization's cloud environment, integration needs, security requirements, and technical capabilities.
8. How does AI improve low-code development?
AI can assist with workflow creation, code suggestions, data transformation, automation, and application development. It can reduce repetitive tasks, but developers and data engineers must review generated outputs for accuracy, security, and reliability.
Q9. Are low-code and no-code platforms suitable for enterprise data pipelines?
They can be suitable when they support the required data volume, integrations, security, governance, monitoring, and performance. For complex environments, organizations often combine visual pipeline tools with custom code and traditional data engineering practices.
Q10. What is the difference between ETL and ELT?
ETL stands for Extract, Transform, Load. Data is extracted from source systems, transformed before loading, and then stored in the destination.
ELT stands for Extract, Load, Transform. Data is extracted and loaded into the destination first, where transformations are performed using the destination platform's processing capabilities.
The right approach depends on the data architecture, processing requirements, and technology stack.
Conclusion
Low-code and no-code platforms are changing how businesses approach application development, data integration, and workflow automation. They help teams simplify repetitive processes, improve collaboration, and make supported data operations more accessible.
However, these platforms are not complete replacements for traditional data engineering. Complex integrations, large-scale processing, data governance, and performance optimization still require technical expertise.
The most effective approach is to select technologies based on business requirements and combine visual development with custom engineering wherever necessary.
With the right data architecture and implementation strategy, organizations can build more efficient, secure, and scalable data workflows in 2026 and beyond.